Operate
Cloud Monitoring
See service health and important changes before they become larger problems.
Discuss your needsService rhythm
- Choose useful signals
- Configure alerts
- Tune from incidents
What it covers.
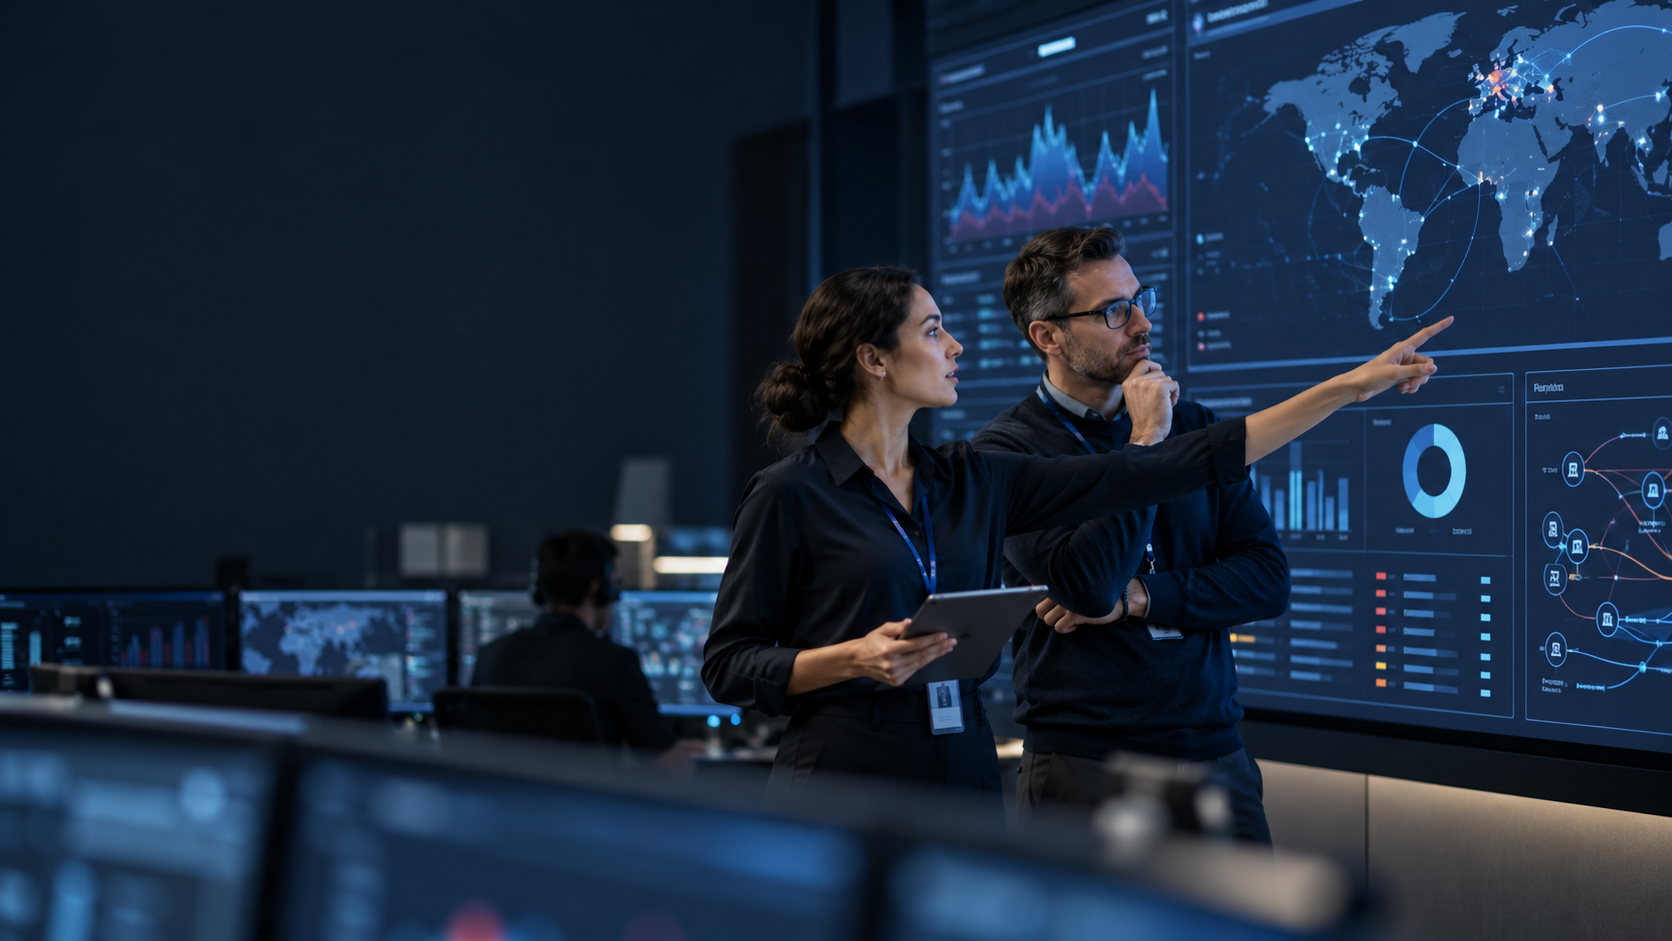
Cloud monitoring gathers signals from applications and cloud resources so teams can detect issues, investigate causes and understand trends.
We identify critical services and useful signals, configure alert routes and dashboards, then review noise and gaps after real incidents.
How it runs
A practical path forward.
We agree on responsibilities, act on what matters and use what we learn to improve the service.
- 01
Choose useful signals
- 02
Configure alerts
- 03
Tune from incidents
What you receive
Practical service outputs.
- Service-level signals
- Actionable alert routes
- Operational review view
Working together
People and systems, in step.
Who this helps
Teams responsible for day-to-day operations, technology continuity and the people who rely on these systems.
Why FlairM
We connect support, systems and business context, with clear communication and a plan for continuous improvement.
Continue exploring
Related services
Questions
Before we begin
How does cloud monitoring begin?
We start by reviewing the current environment, people affected and the outcomes you need, then agree on scope and responsibilities.
Can this work with our current team?
Yes. We define ownership, communication and escalation with your internal team and existing providers before work starts.
How are priorities agreed?
Priorities follow business impact, service dependencies and the scope agreed for the engagement.
Next step
Talk about cloud monitoring.
Tell us what your team needs and we can discuss a practical route forward.